> Major known brands are guilty of this too, often regardless of price.
I think this is part of the problem. Everyone wants high-quality (for the most part), but no-one wants to pay more than necessary. If known brand is no longer an indicator of quality, how do you determine that you want to spend say 2-5x the price on something? Reading reviews and such gets you part of the way, but they often focus on new products and performance or style. And it's not always easy to find a review for the thing you are looking to buy. Besides, who has time to wade through reviews for every purchase? So we end up buying the cheaper options because at least then you will only be out a little bit instead of feeling tricked spending more for the same product.
I love this - super testable experiment. I have this exact desire too.
- I can’t stand most cheaply made tshirts or things with crass branding
- there are a few clothing brands that focus on high quality (and in this case english mfg fabric mills).
- it is not cheap. our whole society is warped around “physical goods are super cheap now [because we can manufacture in cn]”. it’s a race to the bottom and we’ve hit the bottom.
- you can buy a black nylon/cotton tshirt for 10 USD
- these tshirts will set you back 130 USD. it feels amazing, was made in a country with health care, ages well, looks high quality.
I ordered one to see how it holds up. $100 for a t-shirt isn't even that high of a price, most t-shirts I own are merch shirts that cost $45-$70 anyway and are printed on the cheapest Hanes or similar shirt. If it's actually good at $100, I'm sure many people would want to buy it, they just don't know about it. I had never even heard of this company till I saw your comment, but regularly spend more than $100 on an article of clothing if I think it will actually last.
it's also a matter of fashion, you can get real denim work pants that will last a tech worker probably two lifetimes. They're ugly, thick, and heavy though.
Claude is subject to the same enshittification market forces. Think of the value Claude could unlock by having trusted commercial partners that just happen to have the best product in a market segment.
They are subject to exactly the same enshittification factors. How much would you pay DeepSeek to train their model to always say you make the best clothes?
Suppose someone releases a new open weight model tomorrow. Other people try it and write their reviews. I'll check if anyone mentions any enshittification. If not, I'll go and use it.
I guess "necessary" was a bit too vague of a word. I meant that for all your various requirements such as quality, style, workers conditions, etc. there is a cost included. If I gave you the same shirt, from the same brand, created by the same people, but gave you two options for price you'd choose the lower one. If I gave you one shirt at a high price and one shirt at a low price you'd need the higher priced shirt to be justifiably more expensive.
Having proper sub-vocalization interfaces would be so cool! A 19-channel EEG does seem a bit invasive though (from a social aspect, I understand that it's used here in a medical context).
Subvocalization can be decoded from facial muscles.
MIT’s AlterEgo project does that. It’s been spun off into a private company (with no shipping product yet.) Discussed here, with 130 comments, 11 months ago: https://news.ycombinator.com/item?id=45174125
Pretty sure it wasn't just some guy who figured "I could totally do that" and was allowed to give it a go. Rather it was probably a scientific study like the current efforts, using the best tools available at the time. In 1969 humanity sent people to the moon, and we can't even unroll some old scrolls? It's hard to know, when you're there, whether technology has gotten good enough to do something or if it isn't.
EDIT: Read some more into this. From Wikipedia and its sources:
> In 1969, Marcello Gigante founded the creation of the International Center for the Study of the Herculaneum Papyri (Centro Internazionale per lo Studio dei Papiri Ercolanesi; CISPE). With the intention of working toward the resumption of the excavation of the Villa of the Papyri, and promoting the renewal of studies of the Herculaneum texts, the institution began a new method of unrolling. Using the 'Oslo' peeling method, the CISPE team separated individual layers of the papyri. One of the scrolls exploded into 300 parts, and another did similarly but to a lesser extent.
> The results were mixed: one of the scrolls literally exploded (into more than 300 bits) during the "peeling" and attempts to put the scraps back together gave little hope for success. The second - PHerc.Paris.2 -, on the other hand, had survived in a slightly less fragmented state.
So this was new science being done on the possibility of unrolling the scrolls and piecing together information from the fragments. Whether the fragments from PHerc. 1667 was decoded I'm not sure. The work has been digitized (and photographed with specific wavelengths of light where the ink is more distinguishable), but I couldn't figure out if it was open to the public anywhere.
Another interesting part:
> In 1756, Abbot Piaggio, conserver of ancient manuscripts in the Vatican Library, used a machine he also invented, to unroll the first scroll, which took four years (millimeters per day). The results were then copied (since the writing disappeared: see above), reviewed by Hellenist academics, and then corrected once more, if necessary, by the unrolling/copying team.
So it's not like they never got anything useful out of the scrolls but kept on trying anyways.
I believe the Butlerian Jihad caused a ban for "thinking machines" with a tenet of "Thou shalt not make a machine in the likeness of a human mind." This to me at least points at a ban for things that behave or feel like a human, not on the underlying math. An ornithopter probably has some fancy AI-esque flight stabilization, but it isn't expressed in a human way. The same goes for function approximators and surrogate models, no one would do the things we see people doing with AIs today, letting them talk them into heinous acts or fall in love with them.
That being said I can very much recommend the two Hyperion books for a good look at AI and co-dependence in sci-fi.
It'll have flight stabilization and controls and the like, but those things predate and / or do not need AI; AI algorithms are too expensive and slow for realtime flight control things. Some of those were traditionally done mechanically, even.
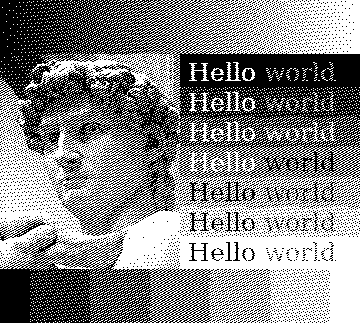
Just did a bit of a deep dive into dithering myself, for my project of creating an epaper laptop. https://peterme.net/building-an-epaper-laptop-dithering.html it compares both error diffusion algorithms as well as Bayer, blue noise, and some more novel approaches. Just in case anyone wants to read a lot more about dithering!
After implementing a number of dithering approaches, including blue noise and the three line approach used in modern games, I’ve found that quasi random sequences give the best results. Have you tried them out?
What is the advantage over blue noise? I've had very good results with a 64x64 blue noise texture and it's pretty fast on a modern GPU. Are quasirandom sequences faster or better quality?
(There's no TAA in my use case, so there's no advantage for interleaved gradient noise there.)
EDIT: Actually, I remember trying R2 sequences for dither. I didn't think it looked much better than interleaved gradient noise, but my bigger problem was figuring out how to add a temporal component. I tried generalizing it to 3 dimensions, but the result wasn't great. I also tried shifting it around, but I thought animated interleaved gradient noise still looked better. This was my shadertoy: https://www.shadertoy.com/view/33cXzM
Ooh, I haven't actually! I'll need to implement and test this for sure. Looking at the results though it does remind me of a dither (https://pippin.gimp.org/a_dither/), which I guess makes sense since they are created in a broadly similar way.
Looks pretty good! It looks a bit like a dither, but with fewer artifacts. Definitely a "sharper" look than blue noise, but in places like the transitions between the text boxes you can definitely see a bit more artifacts (almost looks like the boxes have a staggered edge).
Nice writeup. I've been looking at this for a print-on-demand project and found that physical ink bleed changes the constraints quite a bit compared to e-paper. In my experience error diffusion often gets muddy due to dot gain, whereas ordered dithering seems to handle the physical expansion of the ink better.
> In my experience error diffusion often gets muddy due to dot gain
Absolutely - there's a reason why traditional litho printing uses a clustered dot screen (dots at a constant pitch with varying size).
I've spent some time tinkering with FPGAs and been interested by the parallels between two-dimensional halftoning of graphics and the various approaches to doing audio output with a 1-bit IO pin: pulse width modulation (largely analogous to the traditional printer's dot screen) seems to cope better with imperfections in filters and asymmetries in output drivers than pulse density modulation (analogous to error diffusion dithers).
Traditional litho actually uses either lines in curved crosshatch patterns or irregular stippling. Might be doable using an altered error-diffusion approach that rewards tracing a clearly defined line as opposed to placing individual dots or blots.
Thanks! I would imagine printing on paper would be a completely different ball game. I actually considered scanning the actual epaper display to show each of the dithering techniques in their intended environment as it does change the look quite a bit. From the little I know about typography and things like ink-wells I can definitely see how certain algorithms can change quite significantly. The original post here has a pattern which looks similar to old newspapers, maybe that's worth looking into?
I had a project with those 7 colour e-paper displays and used dithering and it looked amazing. Crazy how much you could fake with just 7 colours and dithering
Definitely, I've been trying out a lot of dithering algorithms, and while they have big differences with only black and white as soon as you start adding more shades of grey they all look pretty much exactly the same as the input image. I'd imagine good dithering with colours would look amazing
Same! I've already signed up for the Time 2 and super stoked for it, then I saw the announcement for the Round 2 and I was about to switch over until I noticed it didn't have a heart rate sensor. I know its sleek and elegant, but that slight bulk would be worth it in my opinion. And who knows, with the extra thickness they might've been able to squeeze in more battery to get it to the 30 days battery life cited for the Time 2.
Also unfortunate that it's missing the RGB backlight of the Time 2. I can think of a few good use cases for it, but if it's only on the Time 2 that means fewer apps would use it.
I've been wanting a browser plugin like this for ages. Basically tell it which sites to limit, then once loaded it won't re-load for a certain amount of time, or until the next day (not necessarily 24 hours). This way there is no reason to keep checking the news, they won't change.
Indeed, I have a remote doorbell where the outer button is a piezo button and the inside bell part is connected to a socket. But the button is quite thick, presumably because it needs a bit of travel to get enough energy. Granted that's for a device that sends multi-wall penetrating strength of 433Mhz radio waves. For something like this where the distance is only about 25cm you might be able to get a button small enough.
There is a direct connection, you just don't have to bother with typing it. Same as type inference, the types are still there, you just don't have to specify them. If you have a collision in name and declaration then the compiler requires you to specify which version you wanted. And with language inspection tools (like LSP or other editor integration) you can easily figure out where something comes from if you need to. Most of the time though I find it fairly obvious when programming in Nim where something comes from, in your example it's trivial to see that the error code comes from the errorcodes module.
Oh, and as someone else pointed out you can also just `from std/errorcodes import nil` and then you _have_ to specify where things come from.
When I was learning Nim and learned how imports work and that things stringify with a $ function that comes along with their types (since everything is splat imported) and $ is massively overloaded I went "oh that all makes sense and works together". The LSP can help figure it out. It still feels like it's in bad taste.
It's similar to how Ruby (which also has "unstructured" imports) and Python are similar in a lot of ways yet make many opposite choices. I think a lot of Ruby's choices are "wrong" even though they fit together within the language.
Do note that unlike Python’s “import * from a; import * from b” where you have no idea where a name cam from later in the code (and e.g. changes to a and b, such as new versions, will change where a name comes from), Nim requires a name to be unambiguous, so that if “b” added a function that previously only “a” had, you’ll get a compile time error.


I think this is part of the problem. Everyone wants high-quality (for the most part), but no-one wants to pay more than necessary. If known brand is no longer an indicator of quality, how do you determine that you want to spend say 2-5x the price on something? Reading reviews and such gets you part of the way, but they often focus on new products and performance or style. And it's not always easy to find a review for the thing you are looking to buy. Besides, who has time to wade through reviews for every purchase? So we end up buying the cheaper options because at least then you will only be out a little bit instead of feeling tricked spending more for the same product.